
A common SEO accident is that the project team is “optimal” and the web page can be opened, but the search performance has deteriorated. Turning to the question “Why isolated web pages are hard to get a stable ranking” is the common cause of the lack of discovery paths, thematic relationships and intra-site power transfers on pages without internal links. On the surface, this does not mean that the search engine is receiving the correct signal.
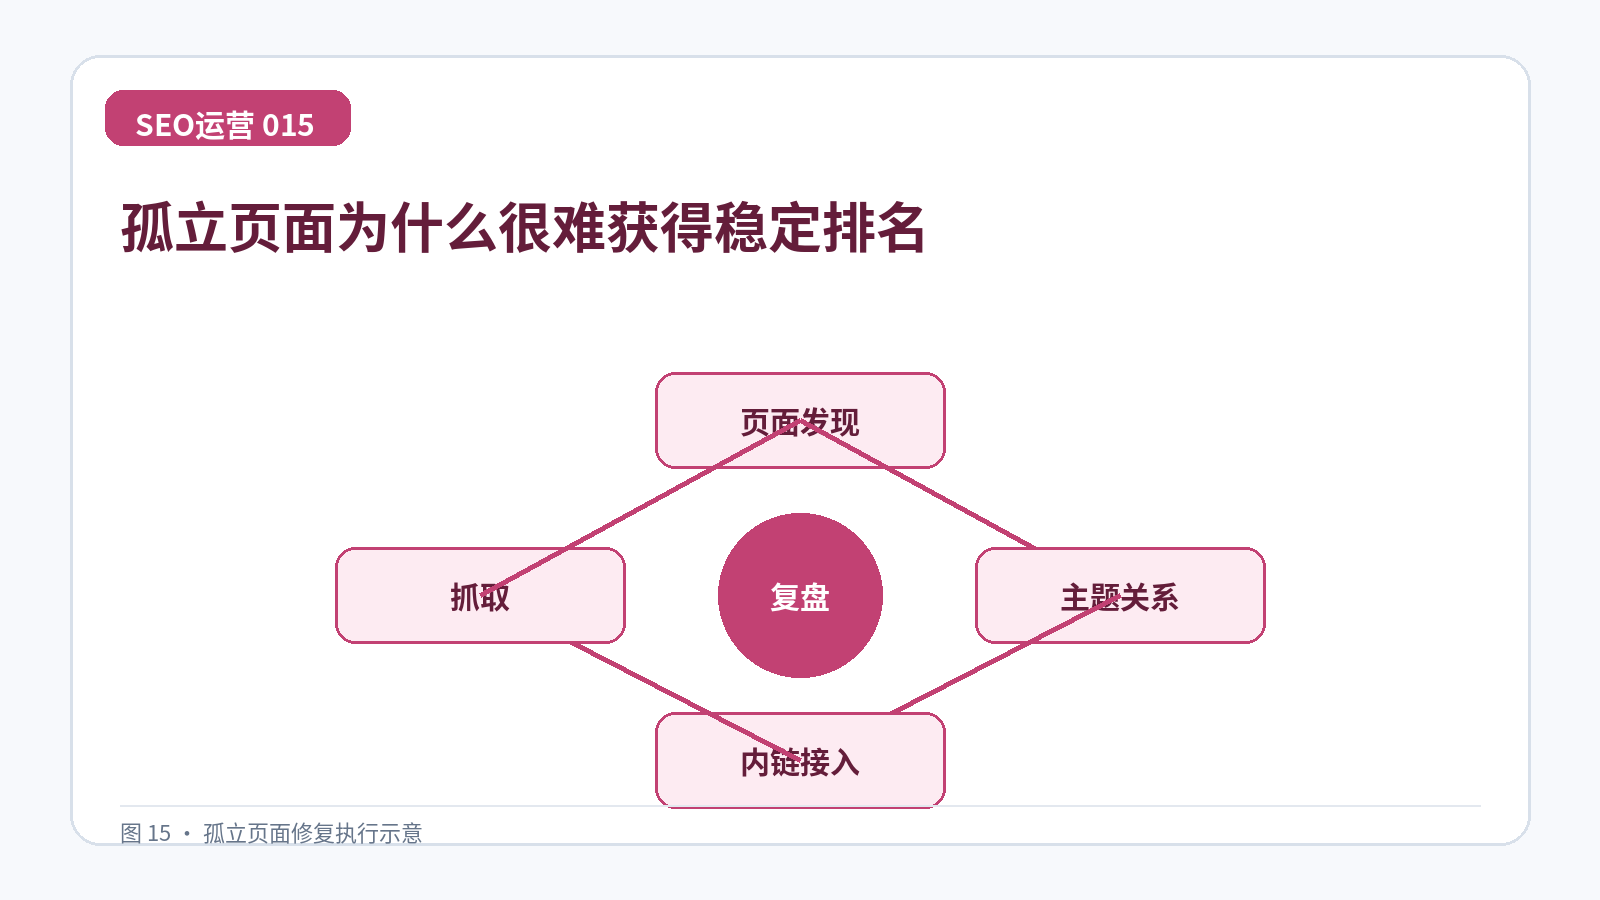
Back to the principle: Site maps can help to discover, but do not replace contextal chains and navigational relationships. Compare web pages, captured HTML, server status and in-site links that browsers see together, often finding reasons faster than repeatedly changing keywords.
The restoration programme is to cross-reference the isolated URLs from reptile data and analysis systems, and to integrate or line down valuable web access columns, topics or related articles; and consolidate or drop-off non-value web pages. Prioritize the restoration of high-flow, high-transformation and important extra-chain URLs and then process long-tailed web pages; each batch maintains a change retention and roll-back version.
Checks whether the depth of hits, the number of internal links, the timing of capture and target queries are improving. If changes are seen only on a single day, do not rush to declare success because retakes, index updates and needs fluctuations take different time.
The follow-up disk must clearly link the footer to the entire site to remove the isolated page, creating low-relevant links and diluted the navigation. Translating the cause of the accident into automatic pre-line verification and manual sampling is more reliable than relying on someone to remember lessons.
At the maintenance level, “Isolated web site restoration” can be added to the quarterly spot-check: randomly selects old and new pages, checking that configurations, text, links, and data are still consistent with current operations. Search rules and product information change, and the correct web page needs to be clearly updated.
In order to prevent the conclusion from remaining in the report, it is recommended that the webpage discovery and capture be made an on-line acceptance item and that the anomaly be judged and repaired at the same time. This way, the new web page will follow the same standard and the old page will be discovered in a timely manner after the template has been changed.